Why AI Blog Idea Generators Give Useless Lists — and a Better Way
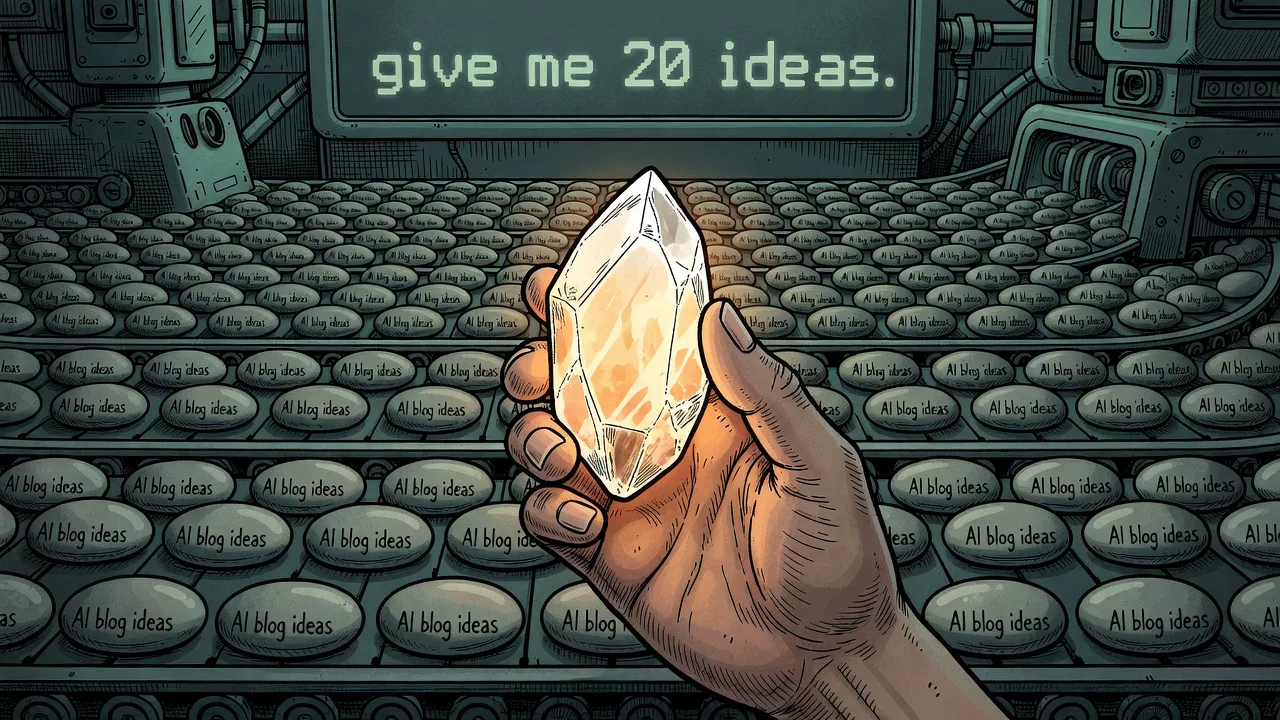
Publishers who open a tab and type “give me 20 blog ideas about [topic]” get a list that feels inert. Not wrong. Just empty. The titles are plausible. The angles are familiar. Publish them and they sit there like a hundred other posts nobody needs.
The quiet problem is not that the model is broken. It is that we keep asking a prediction machine to invent originality, then treat the output like a content calendar. And then we wonder why the AI content idea generator is useless.
This piece names why those lists feel empty, maps the failure modes that turn ideation into a volume game, and offers a grounded alternative: bring a half-formed idea, stress-test it, and use real audience language as your signal. Toward the end I mention a tool I built to structure that signal – but the point is not more ideas. It is better filters.
1. The failed assumption (AI brainstorm = originality)
The operating assumption buried in “give me twenty blog ideas” is that an AI model can generate original, audience-attuned topics on demand – that volume plus fluency equals relevance. It does not.
Large language models are next-token prediction engines. Ask for twenty titles about remote work productivity and the model fishes for the most probable sequences it has seen: meeting overload, home-office ergonomics, “how to stay visible while remote.” All of them already exist.
A 2025 ad-creativity study formalized the drift as a Galton-style regression to the mean: without explicit creative constraints, LLMs lean toward safe, generic phrasing that mirrors the most common patterns in their training data.
That is not a bug – it is the architecture. The model minimizes surprise. A content idea that minimizes surprise is one readers already met elsewhere. Average ideas make average posts. When the feed floods with competent, weightless AI drafts, average is not neutral – it is invisible. The overhead is climbing the noticeability cliff after everyone else published the same thing.
So the first mistake is treating the model as an idea generator rather than a pattern completer. Without a half-formed seed that already carries tension, it hands you the most frictionless titles in its vocabulary. That is not ideation. That is statistical autocomplete. ChatGPT blog ideas are generic because the model defaults to the average; without a seed, you get an average list.

2. Why idea lists regress to the mean
Here is the plain-language version. For each next word, the model picks what appears most often in similar contexts. A blog idea is those high-likelihood choices stitched together. Jagged, contrarian angles – the ones that make a reader stop – are low-probability paths. The model hesitates unless you force the constraint.
The enthusiast might counter, “But volume still wins. If we publish thirty posts a month, we dominate the long tail.” That argument assumes search engines reward sheer volume over topical authority and distinctiveness. They do not.
When five competitors all publish competent but interchangeable “best remote work tips” articles, the ranking lifts vanish. The value of each additional weightless piece approaches zero. You can flood the zone with competent text and still lose. Standing out requires specific friction – proof-of-work, audience insight, a fresh edge – that a bare probability engine cannot mint from a blank prompt. It can only remix what has already been written.
That’s not to say AI can’t assist. It can. But its default mode, when handed a vague creative task, is to serve you the average of all the articles that came before. That’s not originality; that’s the same conclusion a 2026 psychology paper on LLM convergent responses in divergent thinking reached: even diverse large language models converge on strikingly similar responses in creative tasks. The paradox: you can get high fluency and still end up with low novelty. So if you’re feeling that your AI-generated idea list is eerily similar to your competitor’s, trust the feeling. It’s not paranoia. It’s regression.

3. Failure-mode map (separate the ways ideation dies)
To fix this, it helps to name the ways the process falls apart. Here’s my map-not an exhaustive taxonomic tree, but the patterns I see operators trip over again and again.
Volume without a seed. This is the classic “give me 20 blog ideas about X” prompt. No customer language, no friction point, no specific angle you already suspect is interesting. The output is a deck of generic titles pulled from the central mass of the training distribution. It’s easy to generate. It’s also easy to ignore.
Generic shapes. Think best-of lists, tip roundups, recycled how-tos. Even without AI, those formats feel synthetic. But AI amplifies the effect-the sentence structures, the hedges, the relentless “Top 10 Ways to…” cadence. Readers have learned to smell this. They scroll past.
No filter. The moment you accept the first list the model gives you as a content calendar, you’ve abdicated three critical checks: audience fit, search demand, and whether the angle is actually distinguishable from what’s already indexed. The generator isn’t performing those checks. You are. If you skip them, you’re publishing in the dark.
Tool theater. I’ve watched teams swap from one “AI idea generator” to another, tweak prompts, join prompt-pack communities-all while ignoring the one thing that produces viable ideas: collecting actual demand signals. It’s easier to fiddle with a new tool than to sit with messy audience language and distill it into something worth writing. But tool-swapping is a displacement activity, not a strategy. The missing piece is structured conversation signals, not another blank-prompt idea generator.
Model-as-author of the topic. This is the subtlest failure mode. You let the AI pick what you write about-not just help you phrase it-then wonder why the resulting post sounds like everyone else’s. The model becomes the editorial director, and you become the paste-button operator. That inverts the entire creative workflow.
These failure modes share a root cause: treating idea generation as a blank-slate exercise when it should be a signal-following one. The map points toward the fix: stop asking for volume and start bringing your own raw material.

4. What works instead (grounded ideation)
I’m going to walk through a practical loop that I recommend-something you can run next time you’re staring at an empty editorial calendar. It replaces the “20 ideas about X” habit with a sequence that starts from friction, so you can brainstorm without blank-prompt lists.
Bring a half-formed seed. Before you open any tool, you should have a rough topic or observation-something that made you curious, annoyed, or uncertain. Maybe you noticed a pattern in client calls, or a support ticket kept reappearing. That’s your seed. The seed doesn’t have to be fully baked; it just has to carry a little tension.
Stress-test the seed. Instead of asking the AI “give me more ideas like this,” ask: “What’s wrong with this angle? What’s missing? What would make it more specific?” This flips the model from an idea generator into a critical sparring partner. It’s not about getting more output-it’s about pressure-testing the one you have. Research on prospective hindsight (pre-mortems) shows that imagining a piece failed and working backward surfaces more potential failure modes than expanding alone. I apply the same logic to content ideation: pre-mortem your topic before drafting.
Keep a source list, not an idea list. Instead of a backlog of abstract titles, collect real audience wording: questions from customer emails, complaints from support threads, objections in blog comments, recurring phrases in community discussions (anonymized, of course). These are raw demand signals. When you write from a source list, you’re answering the language people actually use-not the language a model guesses they might use. Marketing practitioners have long noted that customer questions are an SEO goldmine: if one person asked, hundreds are searching for answers. Your source list beats a top-of-head idea list every time.
Start from annoyances and micro-frustrations. The best content often comes from what annoys you or your audience about the current state of things. Not ranting-but precise, useful friction. A plumber who’s tired of seeing leaky pipe fixes that ignore the valve problem; a marketer frustrated by attribution advice that ignores incrementality. That kind of specific frustration carries proof-of-work that generic lists can’t fake. Frustrations are everywhere-harnessing them produces passionate, resonant content that drives real engagement.
Expand one real topic into multiple angles. Instead of cold-brainstorming twenty unrelated topics, take one validated seed and explode it into variants: a beginner’s guide, a mistake post, a contrarian take, a process breakdown, a case study. Depth over breadth. A topic cluster with genuine expertise-where you link deeply related articles and cover a space thoroughly-outperforms a spray of shallow posts. Topical depth and internal linking signal authority more effectively than volume alone.
Reverse-brainstorm weaknesses first. Before you invest time in optimizing a draft, ask: “Why would a reader dismiss this piece?” Look for missing objections, edge cases, or undefended assumptions. Then write those in. The model, left to its own, will gloss over uncomfortable uncertainties. You won’t.
Validate audience fit, search demand, and whether only you can write this angle. If a competitor could publish the same title tomorrow with zero change and equal credibility, your angle isn’t sharp enough. A quick SERP check and a gut-check against your source list can help you discard obvious misfires before you write a sentence.
This loop-seed, stress-test, source list, frustrate, expand, reverse-brainstorm, validate-doesn’t require magic. It requires discipline. It’s boring, process-driven, and relentlessly focused on evidence from real audience language. Exactly the kind of thing that outlasts the next algorithm nudge.

5. Soft bridge: conversation-structured ideas (IdeaForge)
When the bottleneck is turning messy community discussions into structured idea briefs, a tool that extracts real conversation signals can shortcut the “collect demand signals” step I described above. That’s why I built IdeaForge-it’s a public-beta tool that scans thousands of community discussions (forums, blogs, communities) and delivers structured ideas, each with an angle, rationale, and actual quote from the source thread. The output isn’t a naked title list; it’s a set of seed briefs grounded in what real people are saying.
I want to be clear about what the tool does and doesn’t do. It does not invent lived experience. It does not generate “original” ideas from a blank prompt. It surfaces and structures signals that already exist in public conversation-like the “3 years fully remote and still no promotion” frustration that became a career-growth idea, or the “built the MVP in a weekend, haven’t launched-what if nobody cares?” thread that surfaces a psychological barrier angle. These are real examples from the live tool, not fabricated narratives. You still apply the human filter. You still decide what’s worth writing. Paste a half-formed topic into IdeaForge, get your structured briefs in under 30 seconds, then immediately run the stress-test from section 4-ask “what’s wrong, what’s missing, what would make it more specific.”
No subscriptions; you get a couple free ideas per search, and full unlocks are $9. No promised rankings, no “unlimited originality” claims-just structured conversation signals that you then stress-test using the loop in section four.
If you already keep a strong source list from your own inbox, support tickets, and client calls, you may not need it. But community, forum, and blog scans can catch language signals outside your current customer base-the gap IdeaForge fills. Either way, the principle holds: you’re better off starting from a real audience sentence than from a zero-context prompt.
6. A one-sitting filter before you write from an AI list
Here’s a quick filter you can run over any idea-generated or self-sourced-before you commit a draft. Walk through these questions, don’t just nod along.
First: did this idea come from a real audience sentence, or from a blank “20 ideas” prompt? If it has no source note-a question you heard, a complaint you read-you’re building on air. Second: could three competitors publish the same title tomorrow with no change? If the answer is yes, the angle isn’t differentiated enough to earn attention. Third: what specific objection, edge case, or micro-frustration makes this idea specific? If you can’t name one, you’re offering a generalization, not a position. Fourth: have I stress-tested the seed by asking “what’s wrong with this?” instead of only expanding it? That reflection often reveals the one missing layer that turns a competent post into a useful one. Fifth: do I have a source note-real wording I can quote structurally-not a fabricated anecdote? Without it, the piece will lack the texture that signals you actually know the space. Sixth: am I about to publish volume to feel productive, or one angle that earns attention? Time is finite; aim for one solid piece that moves the needle rather than five that nobody remembers. Seventh: if I used a conversation-mining tool, did I still apply the human filter-stress-testing, validating, sharpening-or did I just repackage the output?
If you already have a half-formed topic, try running it through IdeaForge – then apply the seven-check filter to see if it holds up.
That filter is my close. Stop buying originality from a probability machine. The AI can remix what’s already been said, but it can’t tell you what you’ve uniquely learned or what your specific audience is struggling with. Ground the seed first-from a real conversation, a real frustration, a real unanswered question-then write. That’s the idea. Everything else is just another list.